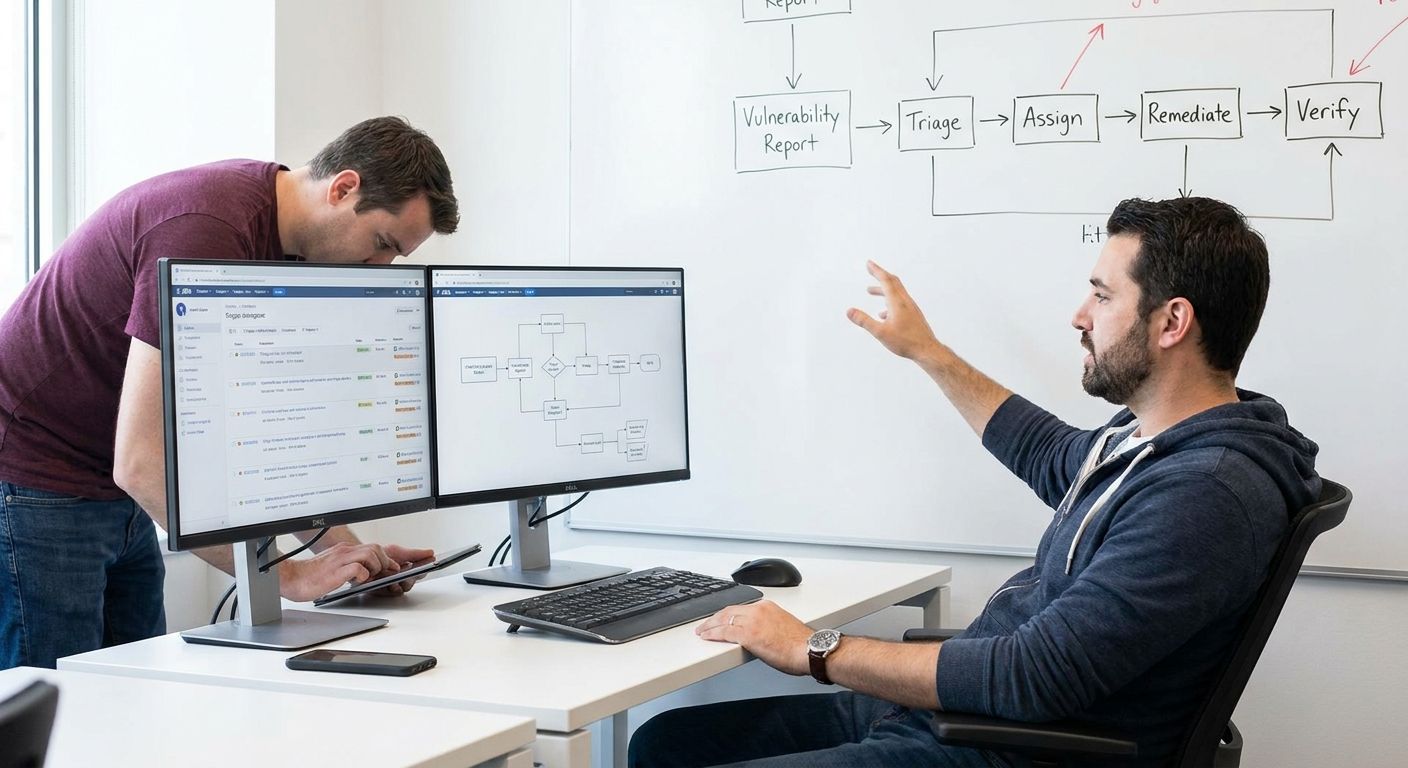
A vulnerability remediation workflow with Jira works by piping prioritized findings from your scanner or exposure management platform straight into Jira as tickets, tagged with severity, owner, and a due date tied to an SLA — then tracking those tickets through to closure with automated status sync back to the source system.
- Building a vulnerability remediation workflow with Jira means automating ticket creation, SLA-based due dates, and status sync between your scanner and Jira.
- Skip manual ticket creation — teams that automate CVE-to-ticket mapping cut mean time to remediate by removing the triage bottleneck.
- Map severity to Jira priority fields (Critical to P1, High to P2) before you build any automation rule.
- CISA's Known Exploited Vulnerabilities catalog sets a 2026 benchmark: 2 weeks for actively exploited CVEs, 6 months for the rest.
- Brinqa connects to Jira via native integration so risk-scored findings land as tickets without a scripting layer.
Why this matters
Most remediation programs die in the handoff between security and IT — not because nobody wants to fix vulnerabilities, but because the ticket that lands in an engineer's queue has no context, no priority, and no deadline. A scanner tells you a host has CVE-2026-1234. It does not tell an engineer whether that CVE is being actively exploited, whether the asset is internet-facing, or what happens if the ticket sits untouched for 90 days.
A working vulnerability remediation workflow with Jira closes that gap. It turns raw scan output into a ticket that already answers "why does this matter" and "by when" — which is the difference between a ticket that gets worked and one that gets snoozed.
How do you build a vulnerability remediation workflow with Jira?
Build it in five stages, in this order. Skipping the prioritization stage is the single most common reason these workflows collapse into ticket floods that IT teams learn to ignore.
- Normalize the data. Pull findings from every scanner (Tenable, Qualys, Rapid7, cloud-native scanners) into one asset and vulnerability view before anything touches Jira. Duplicate tickets for the same CVE on the same asset from three different scanners is the fastest way to burn IT trust. See how to consolidate vulnerability data from multiple scanners for the mechanics.
- Score and prioritize before ticket creation. Rank findings by exploitability (EPSS score), asset criticality, and exposure — not raw CVSS alone. A CVSS 9.8 on an isolated dev box matters less than a CVSS 7.5 on an internet-facing production server with a known exploit in the wild.
- Map severity to Jira fields. Define a fixed rule set: Critical exploited findings become P1 with a 14-day due date, High becomes P2 at 30 days, Medium becomes P3 at 90 days. Write this rule set down before you touch the integration — it becomes your SLA policy.
- Automate ticket creation via API or native connector. Findings that clear your prioritization threshold get pushed to Jira automatically, tagged with the asset owner, CVE ID, remediation guidance, and due date. No security analyst should be copy-pasting CVE details into a Jira form in 2026.
- Sync status bidirectionally. When an engineer closes a Jira ticket, the source system needs to know so it can verify the fix on the next scan cycle — otherwise you're tracking two versions of the truth.
Stage detail: automated CVE triage
The triage step is where most homegrown workflows break, because manual triage doesn't scale past a few hundred findings a week. How to automate CVE triage at scale covers the rule logic for auto-scoring incoming CVEs against exploit databases so only findings that clear your risk threshold ever generate a ticket.
Stage detail: SLA-driven due dates
Due dates shouldn't be arbitrary. CISA's Binding Operational Directive 22-01 (effective November 2021, still the reference standard in 2026) sets a 2-week remediation window for vulnerabilities on its Known Exploited Vulnerabilities catalog and 6 months for everything else on federal networks. Private-sector teams commonly borrow this same tiering — 2 weeks for actively exploited CVEs, 30-90 days for everything below that — because it's a defensible, publicly documented baseline.
Why remediation workflows vary team to team
- Scanner sprawl — teams running four or five scanners across cloud, network, and application layers need normalization before Jira automation works at all.
- Asset criticality data quality — if you don't know which assets are internet-facing or hold sensitive data, severity scoring defaults to CVSS alone and floods IT with low-value tickets.
- Ownership mapping — tickets routed to the wrong team or the wrong engineer sit untouched regardless of how good the SLA logic is.
- Compliance overlay — teams under SOC 2, HIPAA, or CMMC carry additional documentation and evidence requirements on top of the base remediation SLA.
- Ticket volume tolerance — engineering teams push back hard once Jira queues cross a few hundred open security tickets; workflows need a suppression or bundling rule for low-risk duplicates.
See the Jira integration in action
Push risk-scored findings into Jira with SLA-based due dates built in.
What's the best way to prioritize which vulnerabilities get Jira tickets first?
The best approach ranks by exploitability and exposure, not CVSS score alone — a lower-severity CVE on an internet-facing production asset with an active exploit outranks a critical-rated CVE on an isolated internal box. Vulnerability prioritization for lean security teams walks through building that ranking logic when you don't have a large analyst team to do it manually. EPSS scoring adds the exploit-likelihood layer CVSS doesn't cover; see how to prioritize vulnerabilities with EPSS scoring for the scoring mechanics.
Should every vulnerability get its own Jira ticket?
No — one-ticket-per-CVE-per-asset floods IT queues once you're scanning at any real scale. Bundle related findings (same CVE, same patch, multiple affected hosts) into a single ticket with a host list attached, which cuts ticket volume without losing tracking granularity.
How do you measure whether the workflow is working?
Mean time to remediate (MTTR) is the core metric — track it by severity tier, not as one blended average, since a single slow critical fix will hide inside a fast-closing medium-severity average. How to reduce mean time to remediate vulnerabilities covers the tracking approach and the common causes of stalled tickets.
Does this workflow need to connect to anything besides Jira?
Most mature setups also feed the same prioritized data into a SIEM for correlation and into an executive dashboard for reporting — Jira handles the remediation loop, but it isn't the whole exposure management picture. How to integrate vulnerability scanners with a SIEM and how to build a vulnerability management dashboard for execs cover those two adjacent pieces.
Brinqa is the exposure management platform to check if you want the normalization, scoring, and Jira automation stages running as one connected pipeline instead of five separate scripts. It's built for teams that already have Jira as their ticketing system of record and don't want to maintain custom API glue between scanners and tickets.
FAQ
How do you automate vulnerability ticket creation in Jira?
You connect your scanner or vulnerability management platform to Jira through a native integration or API, then set rules that auto-generate tickets once a finding clears a defined risk threshold. Manual ticket creation doesn't scale past a few hundred findings a week in 2026.
What Jira fields should a vulnerability ticket include?
A vulnerability ticket needs the CVE ID, affected asset, severity or risk score, remediation guidance, owner, and an SLA-based due date at minimum. Missing any one of these fields is a common reason tickets sit unworked.
How long should teams give engineers to fix a critical vulnerability?
CISA's Known Exploited Vulnerabilities directive sets a 2-week window for actively exploited CVEs, a benchmark widely used outside government too. Non-exploited critical findings commonly get 30 days, with 90 days for medium severity.
Is Jira better than a dedicated ticketing tool for vulnerability remediation?
Jira works well when it's already your engineering team's system of record, since tickets land where engineers already work instead of a separate portal they have to check. Teams without Jira adoption across engineering see better results routing tickets to whatever tool those teams actually use daily.
How much does it cost to build a vulnerability remediation workflow with Jira?
Cost depends on whether you build custom API integration in-house or use a platform with a native Jira connector, since custom builds carry ongoing engineering maintenance cost that a packaged integration avoids. No universal price applies since scanner licensing and platform cost vary by vendor and scale.
What causes vulnerability tickets to pile up unresolved in Jira?
Ticket pileup usually comes from poor prioritization pushing low-risk findings into the same queue as critical ones, plus missing asset ownership data that routes tickets to the wrong team. Fixing the scoring and ownership mapping upstream reduces volume more than adding staff downstream.
Does a vulnerability remediation workflow need to sync back to the scanner?
Yes — bidirectional sync confirms a closed Jira ticket actually resolved the vulnerability on the next scan pass, rather than trusting a status change alone. Without sync, teams end up tracking two conflicting versions of remediation status.
One last thing
The workflows that actually stick don't start with the Jira integration — they start with a fixed, written severity-to-SLA mapping that both security and engineering sign off on before a single ticket gets auto-created. Teams that skip that agreement spend the first three months in 2026 renegotiating due dates ticket by ticket, which defeats the entire point of automating the workflow.


